The runtime security platform for enterprise AI
Intercept sits between your AI and the damage it could do. It blocks prompt injection, data leaks, and rogue agent actions in real time, before they ever execute. Across text, audio, images, and MCP.
Deploy AI fast. Stop what it shouldn't do.
One platform sits between your AI and the damage it could cause, deciding what's allowed and enforcing it in real time, so teams ship AI fast without shipping the risk. Verifiable evidence comes built in.
Block every threat
Tiered ingress and egress inspection with DLP, inline on production traffic. Prompt injection, leaks, and unsafe output caught before the model sees them. Sub-2ms heuristics; ML only when it matters.
Govern every agent
Capability-scoped authority for every agent and tool call: least privilege by default, revoked the moment behavior drifts. Rogue actions are denied before they run, not flagged after the damage.
Prove it stopped
Every allow, block, and flag is signed and hash-chained into a verifiable receipt: evidence anyone can check, a byproduct of prevention rather than the point.
Agent Security
Capability-scoped authority for every agent and tool call. Each call is evaluated against policy before it executes, with authority revoked when behavior drifts. Least privilege, enforced in real time.
EXPLORE AGENT SECURITY →Policy: Every agent action is checked against your rules (permissions, limits, and context) before it’s allowed to run.
Guard
Tiered detectors inspect every prompt and response, ingress and egress (prompt injection, data leakage, toxic output, and more) with sub-2ms heuristics and ML escalation only when it matters.
EXPLORE GUARD →Scan: Every prompt and response is inspected for injections, leaks, and unsafe content before it reaches your model.
Command
One live console for your AI engineers and SOC. See every model, agent, and decision as it happens, investigate any event in a click, and respond the moment something's off. Every action backed by signed proof.
EXPLORE COMMAND →See: Your engineers and SOC see every model, agent, and decision in one console, and respond the instant something looks wrong.
Attack Simulation
Continuous red-teaming and supply-chain scanning probe your models, prompts, and dependencies with the same techniques real adversaries use, mapped to MITRE ATLAS.
EXPLORE ATTACK SIMULATION →Probe: Your AI is continuously attacked with real adversarial techniques, so weaknesses surface before attackers do.
Discovery & Posture
A live, risk-scored inventory of every model, endpoint, and pipeline running across your organization, including the shadow AI nobody told security about.
EXPLORE DISCOVERY & POSTURE →Found: Every model and agent is discovered, including the shadow AI nobody flagged, and scored for risk.
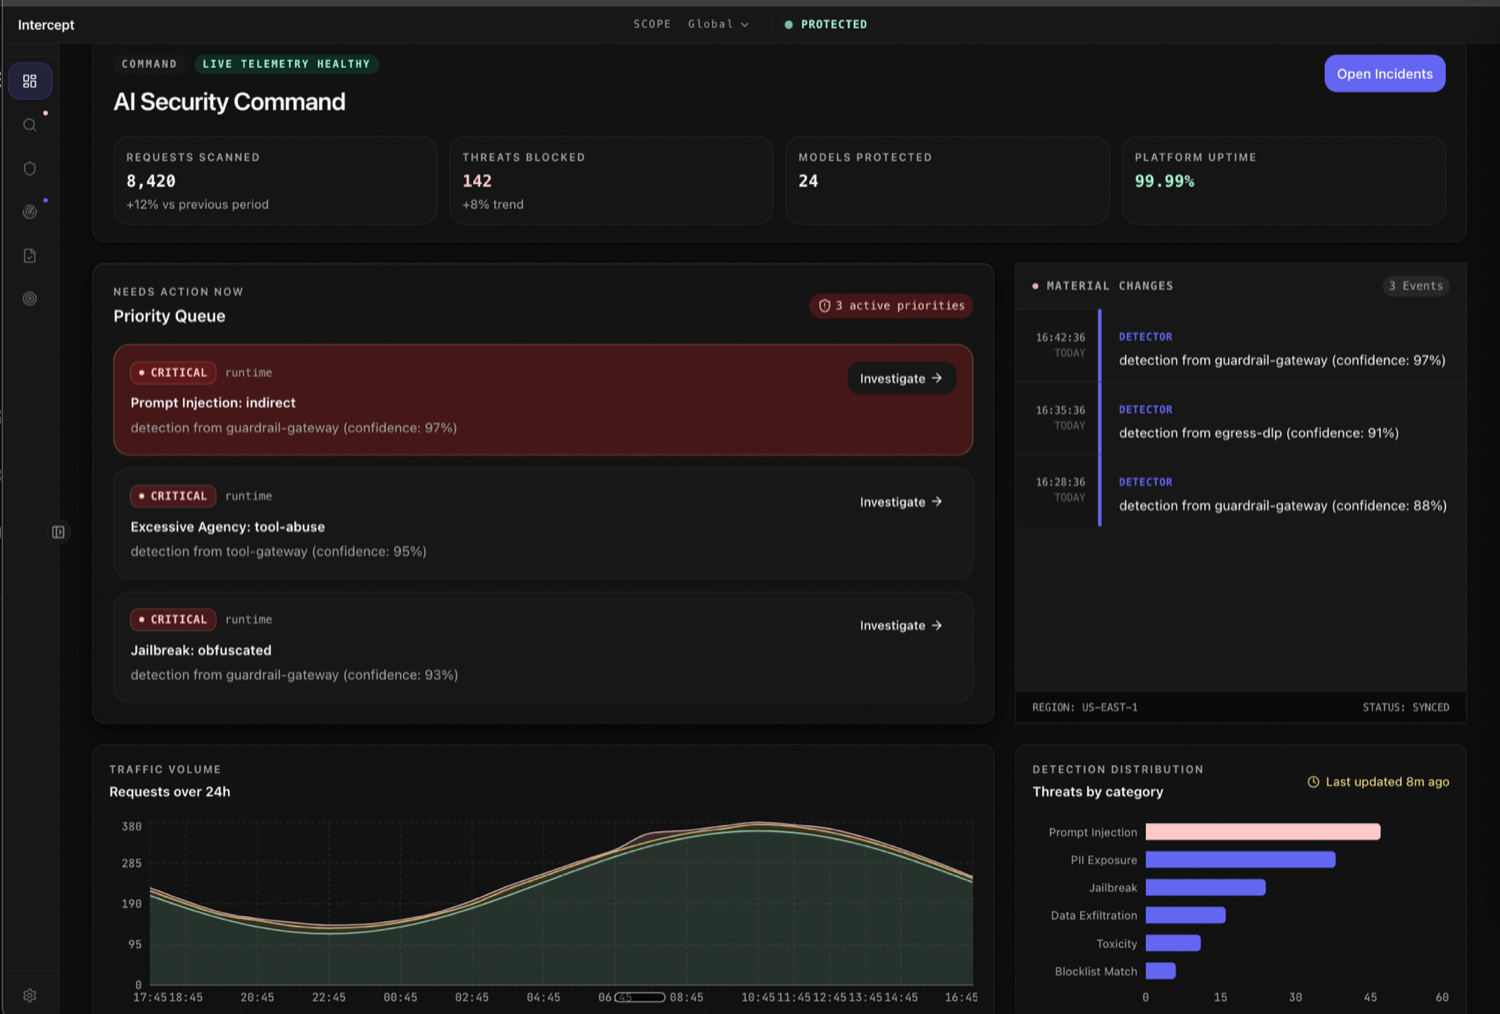
One pane of glass for every verdict
Live agent inventory, policy editor, and the signed decision ledger, in one console your security team actually operates.
From the team securing AI in production
Anatomy of an Indirect Prompt Injection
Memory poisoning makes prompt injection persist for weeks — detonating long after the chat ends. Why classifiers don’t hold, and the controls that bound the damage.
READ →Why audit logs aren't evidence
The difference between a log you trust and a receipt anyone can verify, and why it matters in a review.
READ →Governing tool-calling agents
A practical model for least-privilege authority when your agents can move money and data.
READ →Built for proof
Built by the people securing AI in production. Intercept is built by researchers and security engineers and aligned with the frameworks your auditors already trust: OWASP, MITRE ATLAS, NIST AI RMF, and SDAIA
Why we built Intercept
“Trust us” is not a security posture. As AI starts to act in the real world, every decision an agent makes should be governed, inspected, and provable, not taken on faith.
The Intercept team
Aligned with the standards your auditors already trust
Stop AI threats
before they act
Trusted by security teams, ready for agents. Watch Intercept govern a live agent, block a real attack, and verify a signed decision receipt, all in one session.